Daily brief
OpenAI and Meta Release GPT-5.6
By Steven Sorensen · 11 Jul 2026
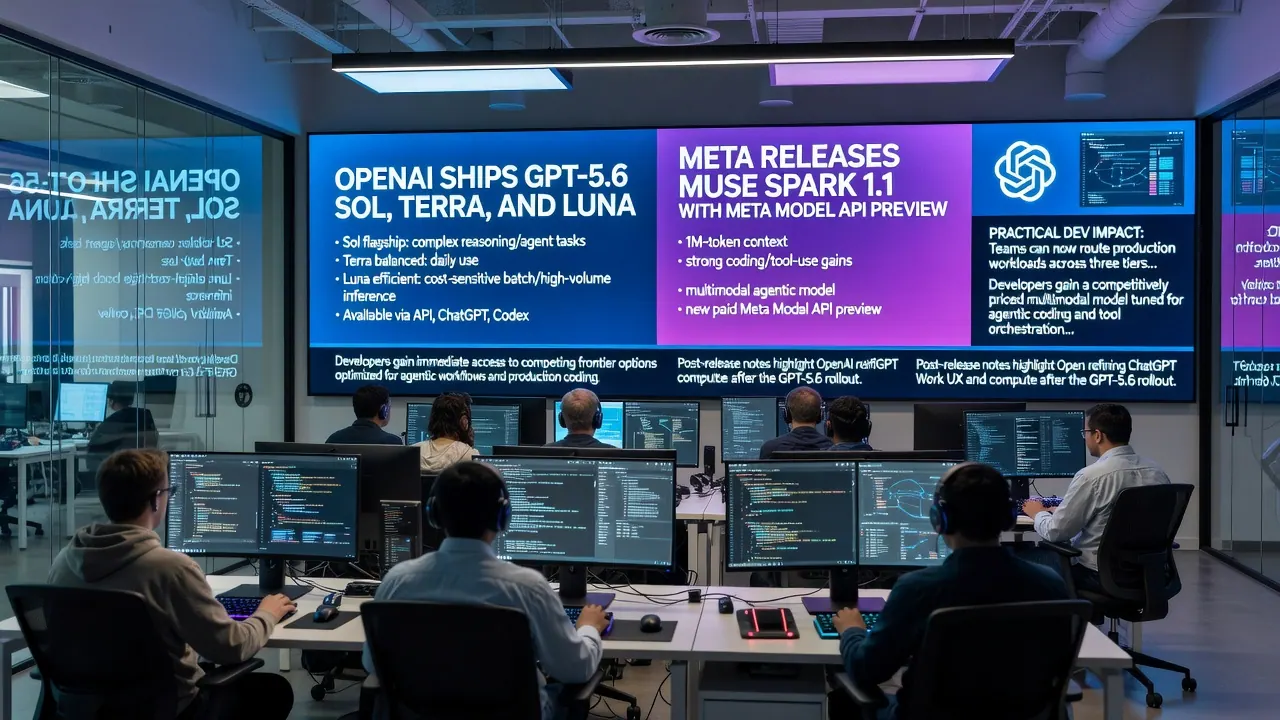
At a glance
## At a glance
- OpenAI broadly released the GPT-5.6 family (Sol flagship, Terra balanced, Luna efficient) on July 9 with API, ChatGPT, and Codex availability.
- Meta launched Muse Spark 1.1 the same day, its multimodal agentic model with 1M-token context, strong coding/tool-use gains, and new paid Meta Model API preview.
- Developers gain immediate access to competing frontier options optimized for agentic workflows and production coding.
- Post-release notes highlight OpenAI refining ChatGPT Work UX and compute after the GPT-5.6 rollout.
OpenAI and Meta both shipped major models on July 9, giving builders fresh choices in the frontier tier exactly when agentic and coding workloads are accelerating. The GPT-5.6 variants target different cost-performance points while Muse Spark 1.1 emphasizes tool use, computer control, and orchestration—directly relevant to teams building multi-step agents or automated development pipelines. These releases arrive after a week of rapid iteration, signaling continued pressure on price, latency, and agent reliability rather than raw scale alone. For professional engineers, the practical shift is toward evaluating these models in real agent loops and IDE integrations rather than waiting for the next headline version. Quiet follow-on coverage today underscores that the industry is absorbing these drops before the next wave.
Top Stories
OpenAI ships GPT-5.6 Sol, Terra, and Luna Practical dev impact: Teams can now route production workloads across three tiers—Sol for complex reasoning/agent tasks, Terra for balanced daily use, and Luna for cost-sensitive batch or high-volume inference—directly in the OpenAI API and Codex.
Meta releases Muse Spark 1.1 with Meta Model API preview Practical dev impact: Developers gain a competitively priced multimodal model tuned for agentic coding and tool orchestration, accessible via the new public-preview API alongside the free Thinking mode in Meta AI.
OpenAI acknowledges ChatGPT Work launch friction after GPT-5.6 rollout Practical dev impact: Early adopters of the enterprise tier should expect rapid UX and cost fixes that will affect how teams manage projects, shared chats, and desktop transitions in the coming days.
Practical Impact Analysis
The simultaneous July 9 drops from OpenAI and Meta intensify competition in the agentic and coding segment. GPT-5.6’s tiered approach lets teams optimize spend without sacrificing capability on frontier tasks, while Muse Spark 1.1’s explicit focus on tool use and 1M-token context positions Meta as a credible third option for orchestration-heavy workflows. Both releases emphasize measurable gains in planning, computer use, and multi-file reasoning—capabilities that directly translate to more reliable autonomous agents and automated refactoring pipelines.
For infrastructure teams, the pricing signals (Luna and Muse Spark positioned near or below recent Haiku-class offerings) accelerate experimentation with model routing and speculative decoding. No major IDE or framework updates landed in the same window, so the immediate engineering work centers on prompt and tool-calling compatibility testing rather than platform migrations. The net effect is a broader, more differentiated frontier tier that rewards careful evaluation over defaulting to a single provider.
Recommended Tutorial Idea
Build a lightweight agent router that evaluates GPT-5.6 Sol vs. Muse Spark 1.1 on a shared coding task using the new APIs.
import os
from openai import OpenAI
# Meta Model API client (preview)
from meta_ai import MetaClient  # placeholder; use official SDK once published

openai_client = OpenAI(api_key=os.getenv("OPENAI_API_KEY"))
meta_client = MetaClient(api_key=os.getenv("META_API_KEY"))

def route_coding_task(task: str):
    # Simple heuristic router
    if "complex" in task.lower():
        model = "gpt-5.6-sol"
        response = openai_client.chat.completions.create(
            model=model,
            messages=[{"role": "user", "content": task}]
        )
    else:
        response = meta_client.generate(
            model="muse-spark-1.1",
            prompt=task,
            thinking_mode=True
        )
    return response.choices[0].message.content if hasattr(response, 'choices') else response

print(route_coding_task("Refactor this multi-file Python service for better error handling"))
Grok Deep Dive
With GPT-5.6 Sol/Terra/Luna and Muse Spark 1.1 both live, how should teams benchmark these models on real agentic coding workflows—especially tool calling, long-context refactoring, and cost-per-task—before standardizing routing logic?
Sources
New: The AI-Dev Prompt Pack, 40 tested prompts for Claude Code, Cursor, and Gemini CLI. See the pack