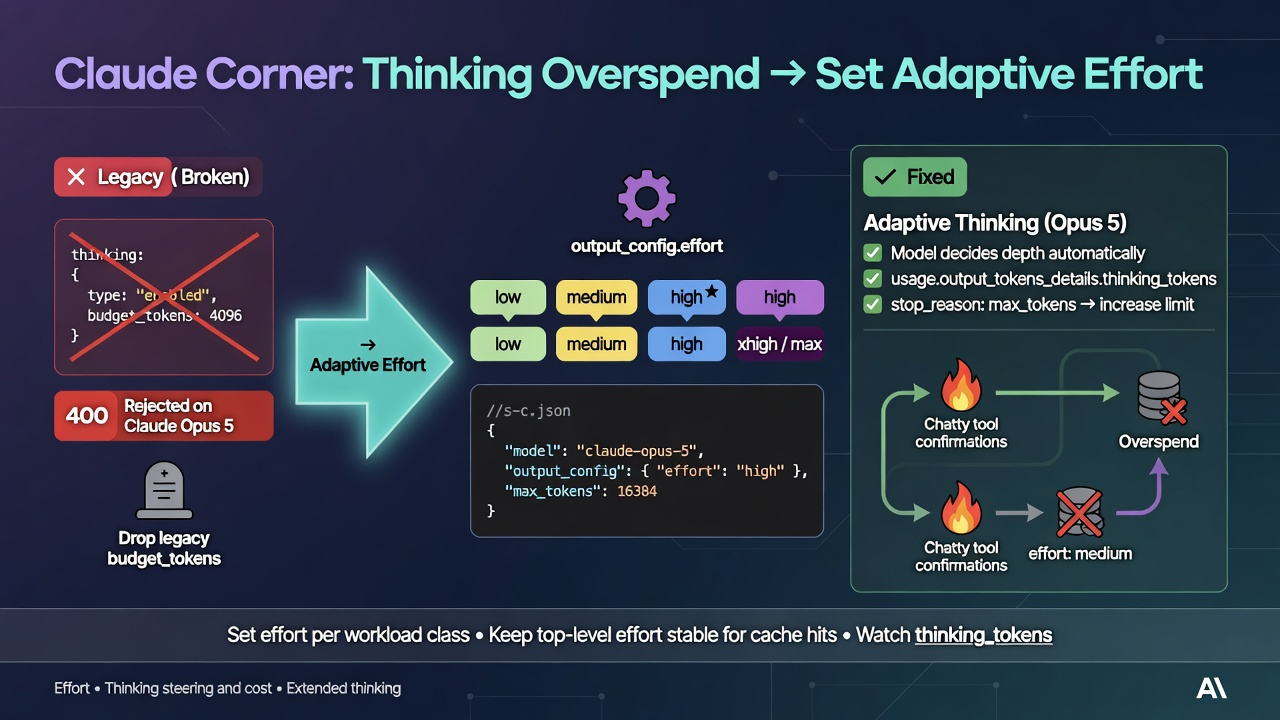
- Drop legacy
budget_tokens. On Claude Opus 5, adaptive thinking is the default and manualthinking.type: "enabled"returns 400. - Steer depth with
output_config.effort(low/medium/high/xhigh/max). Keep that field off thethinkingobject. - Bound cost with a large enough
max_tokens(hard cap on thinking plus text) and readusage.output_tokens_details.thinking_tokens.
Your agent loop still burns tokens on trivial confirms because every turn inherits the same deep-reasoning posture. Fixed thinking budgets either overspend or 400 on current models. The Messages API expects adaptive thinking plus an explicit effort level instead.
Why it matters
Claude Opus 5 runs adaptive thinking by default: the model decides whether and how much to think per request. Effort is soft guidance for that decision. The API default is high, which is fine for hard coding turns and expensive for chatty tool confirmations. Legacy thinking: {type: "enabled", budget_tokens: N} is rejected on Opus 5 and later. Put the level on output_config.effort, leave room in max_tokens for reasoning plus the answer, and keep the same top-level effort across a cached conversation. Changing effort between requests invalidates prompt-cache breakpoints. The one move: set effort per workload class, raise max_tokens when you see stop_reason: "max_tokens", and watch thinking_tokens in usage.
How to set adaptive effort
Use host https://api.anthropic.com/v1/messages, model claude-opus-5, and secrets from the environment. No beta header is required for top-level effort. This tip uses output_config.effort only. Tip 3's output_config.format JSON schema is a different field on the same object.
- 1. Remove any
budget_tokens/thinking.type: "enabled"payload for Opus 5+. Optional: setthinking: {"type": "adaptive"}(equivalent to omitting it on Opus 5). - 2. Set
output_config.effortto match the turn class:lowormediumfor routine steps,high(default) for complex work,xhighormaxfor long agentic coding. - 3. Size
max_tokensfor thinking plus visible text. Atxhigh/max, start large (docs often suggest on the order of 64k) and tune from evals. - 4. After HTTP 200, inspect
stop_reasonandusage.output_tokens_details.thinking_tokens. If you hitmax_tokens, raise the cap or lower effort.
#!/usr/bin/env bash
set -euo pipefail
: "${ANTHROPIC_API_KEY:?Set ANTHROPIC_API_KEY in your environment}"

# Adaptive thinking (default on claude-opus-5) + soft effort steer.
# Do NOT put effort inside thinking. Do NOT send budget_tokens on Opus 5+.
curl -sS https://api.anthropic.com/v1/messages \
  -H "content-type: application/json" \
  -H "x-api-key: ${ANTHROPIC_API_KEY}" \
  -H "anthropic-version: 2023-06-01" \
  -d '{
    "model": "claude-opus-5",
    "max_tokens": 16000,
    "thinking": {"type": "adaptive"},
    "output_config": {"effort": "medium"},
    "messages": [
      {
        "role": "user",
        "content": "List three trade-offs of caching HTTP responses at the edge. Keep it short."
      }
    ]
  }'
# Check stop_reason. If max_tokens, raise max_tokens or drop effort.
# Bill from output_tokens; thinking_tokens in output_tokens_details is the reasoning slice.
# Hold top-level effort steady inside a prompt-cached session.
Gotchas
- Do not pass
"adaptive"as an effort value. Adaptive is a thinking mode. Effort levels arelow,medium,high,xhigh, andmax. - On Claude Opus 5,
thinking: {"type": "disabled"}with effortxhighormaxreturns 400. Prefer lower effort with thinking left on. - Changing top-level
output_config.effortbetween turns busts prompt-cache prefixes. For mid-conversation changes on supported models, use the per-message beta path instead of flipping the top-level field every turn. - Effort steers thinking volume more than visible reply length on Opus 5. Prompt for brevity when you need short prose.
Recommended AI prompt
Copy this paragraph into ChatGPT, Claude, Gemini, Grok, or whatever you use.
You are helping me migrate a Messages API agent from fixed thinking budgets to Claude Opus 5 adaptive thinking. Use Anthropic effort and extended-thinking docs. I need output_config.effort (not budget_tokens), thinking type adaptive or omitted, max_tokens sized for thinking plus text, checks for stop_reason max_tokens, usage.output_tokens_details.thinking_tokens, and a note that changing top-level effort invalidates prompt cache. Produce a checklist plus a minimal curl or Python snippet with model claude-opus-5, host https://api.anthropic.com/v1/messages, and env-based ANTHROPIC_API_KEY only.
Sources: Effort · Thinking steering and cost · Extended thinking · Thinking overview
1 thought on “Claude Corner: Thinking Overspend → Set Adaptive Effort”