Daily brief
Microsoft MAI Models and
By Steven Sorensen · 6 Jun 2026
At a glance
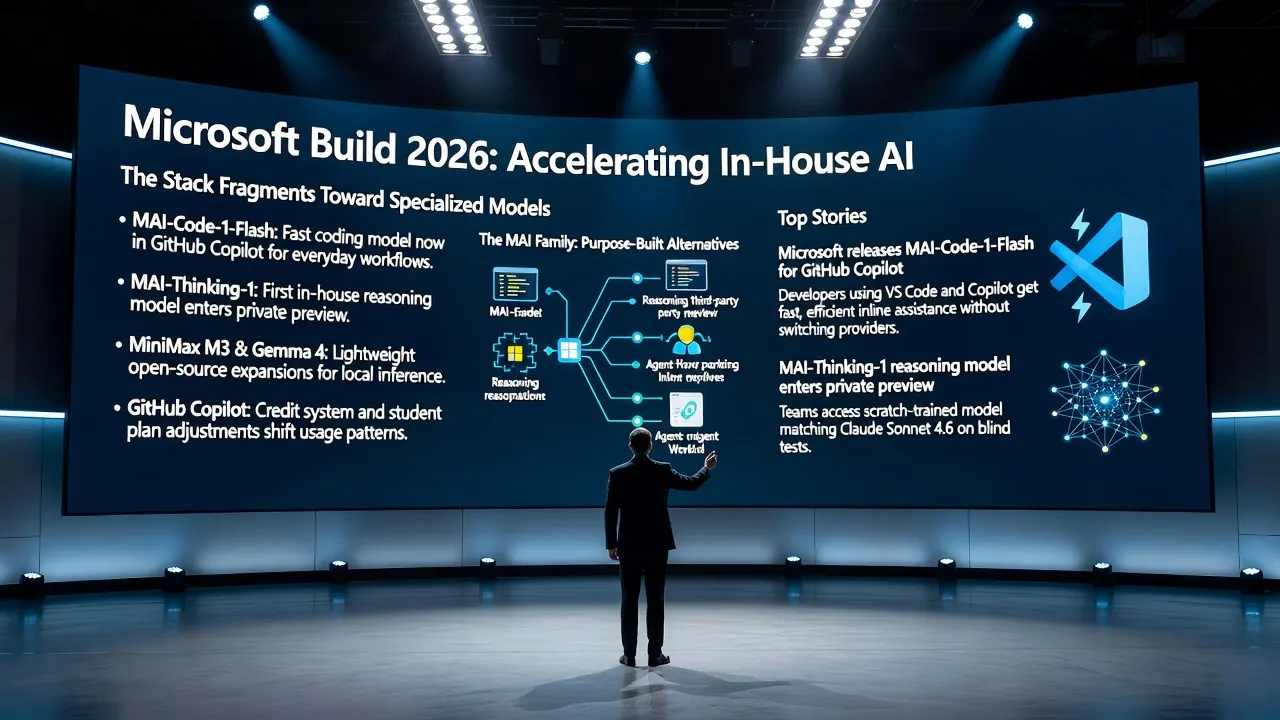
## At a glance – Microsoft shipped MAI-Code-1-Flash, a fast coding model now rolling out in GitHub Copilot for everyday workflows. – MAI-Thinking-1, Microsoft’s first in-house reasoning model trained from scratch on enterprise data, enters private preview. – MiniMax M3 lightweight open-source model and Gemma 4 family updates expand efficient local and multimodal options for devs. – GitHub Copilot credit system and student plan adjustments take effect, shifting usage patterns for free and paid tiers.
Microsoft’s Build 2026 announcements mark a clear acceleration in in-house model development, with direct integration into the tools millions of developers already use daily. The MAI family delivers purpose-built alternatives that reduce reliance on third-party frontier models for high-volume tasks like code completion and reasoning. At the same time, open-weight releases such as MiniMax M3 and ongoing Gemma 4 optimizations keep lowering the barrier for local, cost-efficient inference. These moves coincide with GitHub Copilot’s billing refinements, forcing teams to re-evaluate model routing and credit allocation in production agents and IDEs. For builders, the signal is unmistakable: the stack is fragmenting toward specialized, provider-native models that reward careful evaluation on real coding and agent benchmarks rather than blanket adoption of the largest available LLM.
Top Stories
Microsoft releases MAI-Code-1-Flash for GitHub Copilot Practical dev impact: Developers using VS Code and Copilot now get a fast, inference-efficient coding model tuned specifically for inline assistance and everyday refactors without switching providers.
MAI-Thinking-1 reasoning model enters private preview Practical dev impact: Teams gain access to Microsoft’s first scratch-trained reasoning model that matches or exceeds Claude Sonnet 4.6 on blind tests and SWE-bench coding tasks, available via Microsoft Foundry.
MiniMax M3 lightweight open-source model ships Practical dev impact: Builders can self-host a compact, high-performance open-weight model with competitive pricing for RAG and agent workloads that previously required larger proprietary systems.
Gemma 4 QAT variants optimize for mobile and laptop deployment Practical dev impact: Local-first development gains stronger multimodal options that run efficiently on consumer hardware, enabling offline prototyping and edge agent experiments.
Practical Impact Analysis
Microsoft’s dual release of MAI-Code-1-Flash and MAI-Thinking-1 signals a strategic push toward vertically integrated AI tooling. Copilot users benefit immediately from a specialized small model optimized for high-frequency interactions, while heavier reasoning workloads can route to MAI-Thinking-1 where it demonstrates strong results on enterprise benchmarks. This reduces latency and cost for routine tasks and gives teams a credible alternative to Anthropic or OpenAI defaults inside the Microsoft ecosystem.
Open-source momentum continues with MiniMax M3 and Gemma 4 refinements, lowering the cost of local inference and multimodal agents. Developers running on laptops or edge devices now have more viable options for privacy-sensitive or offline RAG pipelines.
Copilot’s June 1 credit adjustments add friction for heavy users and students, encouraging more deliberate model selection and hybrid routing strategies. Overall, the week reinforces a shift toward task-specific models and careful observability rather than relying on a single frontier provider. Teams that instrument routing logic and benchmark against SWE-bench-style suites will extract the most value.
Recommended Tutorial Idea
Build a lightweight agent that routes coding queries to MAI-Code-1-Flash via GitHub Copilot’s new model access while falling back to MAI-Thinking-1 for complex reasoning steps.
from langgraph.graph import StateGraph, END
from typing import TypedDict, Literal

class AgentState(TypedDict):
    query: str
    code_response: str
    reasoning_response: str
    final_output: str

def route_query(state: AgentState) -> Literal["code", "reason"]:
    if "refactor" in state["query"].lower() or len(state["query"]) < 100:
        return "code"
    return "reason"

def call_mai_code(state: AgentState):
    # Placeholder: integrate with Copilot API or local proxy
    state["code_response"] = f"MAI-Code-1-Flash: Quick refactor suggestion for {state['query']}"
    return state

def call_mai_thinking(state: AgentState):
    # Placeholder: Microsoft Foundry preview call
    state["reasoning_response"] = f"MAI-Thinking-1: Deep analysis of {state['query']}"
    return state

def synthesize(state: AgentState):
    state["final_output"] = state.get("code_response") or state.get("reasoning_response")
    return state

workflow = StateGraph(AgentState)
workflow.add_node("code", call_mai_code)
workflow.add_node("reason", call_mai_thinking)
workflow.add_node("synthesize", synthesize)
workflow.set_conditional_entry_point(route_query, {"code": "code", "reason": "reason"})
workflow.add_edge("code", "synthesize")
workflow.add_edge("reason", "synthesize")
workflow.add_edge("synthesize", END)

app = workflow.compile()
result = app.invoke({"query": "Refactor this function for performance"})
print(result["final_output"])
Grok Deep Dive
Today’s releases from Microsoft highlight a maturing in-house model strategy that directly impacts Copilot users and agent builders; how would you design a production routing layer that intelligently switches between MAI-Code-1-Flash for speed, MAI-Thinking-1 for depth, and open models like MiniMax M3 for cost or privacy, while tracking SWE-bench and latency metrics in real time?
New: The AI-Dev Prompt Pack, 40 tested prompts for Claude Code, Cursor, and Gemini CLI.
See the Prompt Pack