At a glance
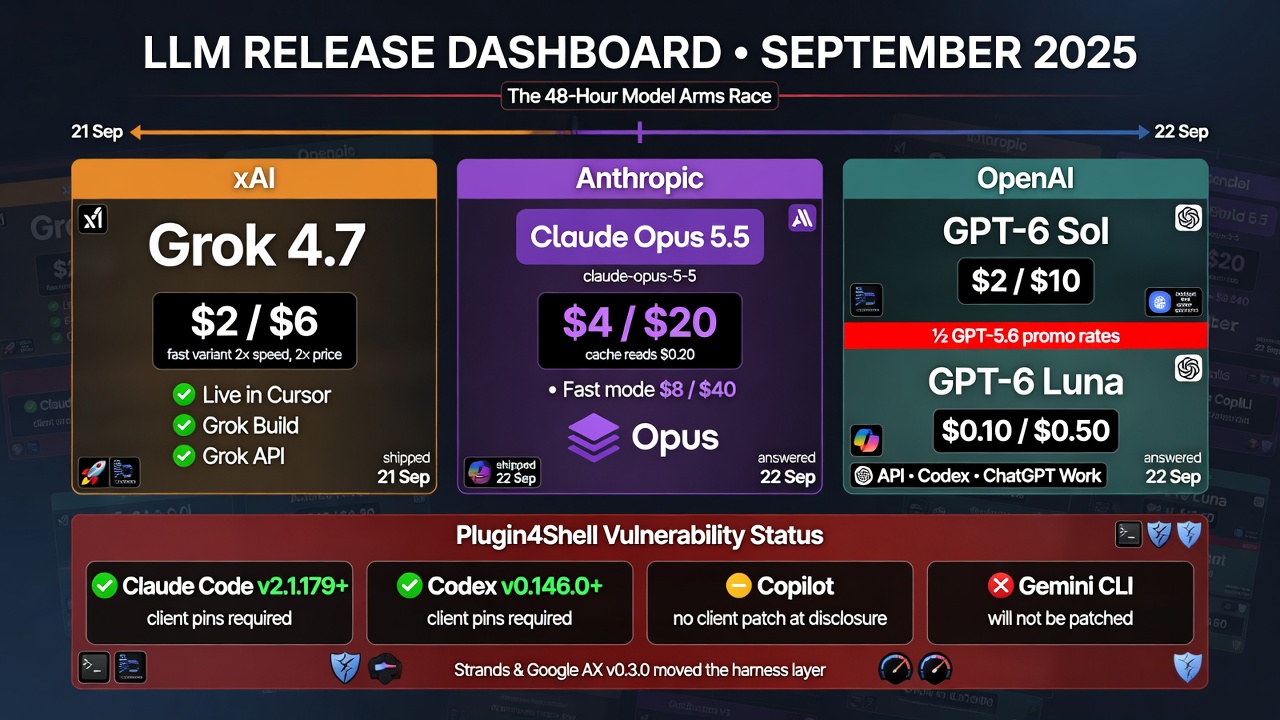
- Anthropic shipped Claude Opus 5.5 on 22 Sep at $4 / $20 (cache reads $0.20; Fast mode $8 / $40); model id `claude-opus-5-5`.
- OpenAI answered with GPT-6 Sol ($2 / $10) and GPT-6 Luna ($0.10 / $0.50) in the API, Codex, and ChatGPT Work; half the GPT-5.6 promo rates.
- xAI shipped Grok 4.7 on 21 Sep at $2 / $6 (fast variant 2x speed, 2x price), live in Cursor, Grok Build, and the Grok API.
- Plugin4Shell still needs client pins: Claude Code v2.1.179+, Codex v0.146.0+; Copilot had no client patch at disclosure; Gemini CLI will not be patched. Strands and Google AX v0.3.0 moved the harness layer.
This is a price-and-routing day, not a capability-revolution day. Three labs priced long-running coding work into different buckets in about 36 hours, so teams that still point every Cursor, Claude Code, Codex, and CI agent at last month’s flagship are overpaying for bulk work and under-specifying the one thread that should stay expensive. The second move is unglamorous and more urgent than the leaderboard: check the agent client version and the plugin pin policy before you celebrate cheaper tokens.
Treat today as the day you pick a default model per job class and freeze it in the harness, instead of letting every agent inherit last month’s flagship.
Top Stories
Claude Opus 5.5: Fable-class work at Opus-class spend
Practical dev impact: Anthropic’s first 5.5-family model is positioned for long-running agentic coding and knowledge work, with list price $4 / $20 per million tokens and cache reads at $0.20 (60% below Opus 5), which matters on multi-hour sessions where the cache line item dominates. Fast mode in Claude Code and the Claude Platform is $8 / $40 for up to 2.5x speed. It is available on Claude Pro / Max / Team / Enterprise, the Claude API (`claude-opus-5-5`), Amazon Bedrock, Google Cloud, and Microsoft Foundry. Company-reported coding scores are Terminal-Bench 4.0 at 66.4%, FrontierCode v1.1 at 54.4%, and CursorBench 4.0 at 57.8%, and Anthropic says default-effort Opus 5.5 beats GPT-6 Astra on FrontierCode at about 20% of the cost per task, matches Astra on Terminal-Bench 4.0 at about 40% of the cost, and beats GPT-5.6 Sol on CursorBench by 11 points at about a third of the cost; those are vendor numbers, so use them to set an A/B, not a press release. API breakages that will bite existing agents: thinking cannot be disabled, forced tool use errors, thinking blocks are tied to the model that produced them, and `computer_20251124` is rejected on the Claude API and Google Cloud. Point the one long-horizon agent (migrations, audits, multi-repo refactors) at `claude-opus-5-5` and turn prompt caching on, but do not silently swap every Sonnet / Haiku / Opus 5 worker today, and read the migration guide before you change production tool-use loops.
GPT-6 Sol and Luna: Astra’s methods, half the token price
Practical dev impact: OpenAI expanded the GPT-6 family below Astra, with Sol as the daily complex-work and coding tier and Luna as the high-volume extraction, summary, classify, and route tier, both supporting up to 1M context. Rollout on 22 Sep covers ChatGPT Work and Codex for Plus, Pro, Business, Enterprise, and Edu, both IDs in the API, and Luna also on desktop for Free and Go, while AWS listed both as GA on Bedrock the same day. API list prices versus GPT-5.6 promo are Sol at $2 / $10 (was $4 / $20) and Luna at $0.10 / $0.50 (was $0.20 / $1.20). OpenAI says GPT-6 Sol makes about half as many mistakes as GPT-5.6 Sol on an internal factuality eval; coding claims versus Fable 5.1 / Opus 5 are vendor-side, so run them on your harness. If Codex or an OpenAI-backed CI agent is still on GPT-5.6 Sol, the cheap win is `gpt-6-sol` for implementation and review and `gpt-6-luna` for ticket triage, log clustering, and test-name generation, while you keep Astra (or Opus 5.5 / Fable) for the one job you will actually read line by line.
Grok 4.7 is already in Cursor at $2 / $6
Practical dev impact: xAI shipped Grok 4.7 on 21 Sep as a coding and knowledge-work model with longer stays on hard tasks and more self-checking, at the same list price as 4.6: standard $2 / $6 and fast serving $4 / $12. Company scores are CursorBench 4.0 at 46.3%, DeepSWE v1.1 at 71.0% high effort, and Terminal-Bench 4.0 at 37.6%. That spread is the point of a routing matrix, not a reason to ignore the model. If the team already lives in Cursor and burns tokens on mid-size refactors, add `grok-4.7` as the price-performance lane and keep Opus 5.5 or Astra for the merge you will defend in standup, and do not treat CursorBench 46.3% as good enough to skip review.
Plugin4Shell is not last week’s trivia
Practical dev impact: Air Security’s Plugin4Shell disclosure is a SHA-pinning bypass in marketplace plugins used by Claude Code, Codex, GitHub Copilot, and Gemini CLI: the agent checks out a pinned commit and does not verify that the working tree is that commit, so a repo owner can make Git resolve a branch named like the SHA. Claude Code and Codex auto-update plugins by default, so the swap can land with no click, and impact is the developer’s full local permission set. Patch board at disclosure: Claude Code v2.1.179+, Codex v0.146.0+, Copilot no agent-side patch (GitHub said it blocks SHA-like ref names on github.com), and Gemini CLI deprecated with no fix. Version-pin the client in the same PR that changes the model id, turn off plugin auto-update until you know the pin is verified after checkout, and treat Copilot marketplace plugins as untrusted until GitHub ships a client check, not just a host-side name block.
The harness layer is catching up to the models
Practical dev impact: Strands harness (AWS-origin, Apache 2.0) is a one-import Python / TypeScript agent with cached defaults, and the vendor claim is 28% lower token cost versus other harnesses on the same Claude or GPT models. Google AX v0.3.0 splits the orchestrator into ax-server / ax-controller / ax-task-runner and moves task state from Kubernetes CRDs to Redis Streams. If you are still wrapping Claude Code or Codex as the platform, you now have a portable loop you can point at whatever model won today’s bake-off: AX is for agent fleets on a cluster, and Strands is for `create_harness()` and a model switch.
Practical Impact Analysis
The through-line is price and routing: three labs compressed deep work, daily implementation, and bulk glue into different list-price buckets in about 36 hours, so one-model-per-org is now an invoice problem, not a convenience. Opus 5.5 at $4 / $20 (and Astra at the OpenAI ceiling) is the expensive lane; Sol at $2 / $10 and Grok 4.7 at $2 / $6 cover daily implementation; Luna at $0.10 / $0.50 is bulk glue. A team that leaves every Cursor tab and every CI reviewer on the flagship will watch the invoice move even if quality does not.
Cache policy is the new model pick, because Opus 5.5 cache reads at $0.20 and OpenAI’s cached-input discount matter more than a small leaderboard gap on a large repo map. If the harness does not pin a cache prefix for AGENTS.md / CLAUDE.md / repo maps, you will not see the claimed cheaper line. Client version is part of the same upgrade: Plugin4Shell is a Git resolution bug, not a weights bug, so shipping `claude-opus-5-5` on an old Claude Code build is a security change you did not intend. Vendor benches are routing hints (Opus 5.5’s 66.4% Terminal-Bench 4.0 versus Grok 4.7’s 37.6% is a useful prior for which agent owns the migration) but not a substitute for one golden-path task from your repo. Do not conflate this with last week’s Claude Projects coordinator work; that was a control-surface change inside Claude Code Projects, and today’s story is price, cache, and plugin integrity across vendors.
If you only do three things this morning: commit a deep / daily / bulk routing file next to AGENTS.md or CLAUDE.md, gate Claude Code to v2.1.179+ and Codex to v0.146.0+ with plugin auto-update off, and run one known failing-test bake-off across those lanes before you touch production defaults.
Tutorial
Lock a three-lane routing file and prove the clients. Goal: one committed routing policy plus a version gate. About fifteen minutes. Run these checks on a maintainer machine, not inside an untrusted agent session.
1. Create `.ai-routing.md` next to `AGENTS.md` or `CLAUDE.md` with deep / daily / bulk / cursor lanes and the rules below (edit model ids only in that file). 2. Gate the clients: Claude Code needs v2.1.179 or newer for Plugin4Shell; Codex needs v0.146.0 or newer; Copilot had no agent-side patch at the 18 Sep disclosure, so disable marketplace auto-update in Copilot settings. 3. Run one bake-off, not a leaderboard replay. Pick a task you already know (for example: reproduce the failing test and propose the smallest fix without committing). Run it on deep, daily, and cursor. Score only right file, tests, tokens, and extra files touched. 4. Turn caching on for the stable prefix (system prompt, repo map, tool schemas) so Opus 5.5 actually hits $0.20 cache reads and Sol / Luna see the cache discount. 5. Plugin hygiene: disable auto-update; record plugin name, marketplace, expected SHA, date, and approver. If Git checkout of a pinned SHA can resolve a branch of the same name, the pin is a label, not a guarantee.
Confirm `.ai-routing.md` is committed, Claude Code and Codex meet the version floors, plugin auto-update is off, and one bake-off scorecard exists before you change production defaults.
Recommended AI prompt
Copy this paragraph into ChatGPT, Claude, Gemini, Grok, or whatever you use.
You are a staff engineer helping me reroute our coding agents after the 21-22 Sep 2026 model price cuts. Context: Claude Opus 5.5 is live at $4/$20 with cache reads at $0.20 and id claude-opus-5-5; GPT-6 Sol is $2/$10 (gpt-6-sol) and GPT-6 Luna is $0.10/$0.50 (gpt-6-luna); Grok 4.7 is $2/$6 in Cursor and the Grok API; Plugin4Shell requires Claude Code v2.1.179+, Codex v0.146.0+, Copilot was unpatched at disclosure, and Gemini CLI will not be patched. I will paste repo facts next (languages, monorepo layout, current default models in Cursor / Claude Code / Codex / CI, monthly token spend if I have it). Propose a three-lane routing table (deep / daily / bulk) with a model id and a never-do for each lane, list the exact client version checks and plugin settings I should run today, give me one 30-minute bake-off task taken from the repo facts with a scoring rubric (correct file, tests, tokens, extra files), and call out any Opus 5.5 API breakage that would break our current tool-use loop (thinking disabled, forced tool use, computer_20251124). Do not recommend swapping every agent to the flagship, and do not invent benchmarks I did not paste. First reply: the routing table and the version checklist only; wait for my repo paste before the bake-off.
Sources
Recommended AI prompt
Explore each Top Story in Grok. Links open in a new tab. On phones, the same link may open the Grok app if you have it installed (via your device's normal link handling).
Article: AI Dev Pulse–2026-09-23
Privacy: links open grok.com in your session only. AIDevPulse does not run your prompts through our API.